Natural Language Processing · M2 · formulas
Viterbi decoding: compare incoming paths, keep the best, trace back
HMM & decoding
Formulas explained through full worked examples
The Viterbi algorithm finds the most likely hidden-state sequence for a fixed observation sequence. At each position, it keeps the best path ending in each state. This is safe because, under the HMM assumptions, future extensions depend on that ending state, not the discarded details of the prefix.
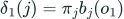 LaTeX:
\delta_1(j)=\pi_jb_j(o_1)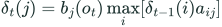 LaTeX:
\delta_t(j)=b_j(o_t)\max_i[\delta_{t-1}(i)a_{ij}]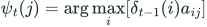 LaTeX:
\psi_t(j)=\arg\max_i[\delta_{t-1}(i)a_{ij}]| Symbol | Meaning in ordinary words |
|---|---|
| δₜ(j) | Score of the best prefix that ends in state j at position t. |
| ψₜ(j) | Previous state that supplied that best prefix; keep it as a backpointer. |
| max | Choose the larger candidate score; do not add. |
| argmax | Remember which previous state won, rather than only its value. |
Do not choose the best state independently at each word. The best last state can come from a different best predecessor than a local guess. Backpointers recover one consistent complete path. If scores tie, either tied path is optimal under the model; state the tie.
Question. Use an HMM with π(H)=0.8, π(C)=0.2, transitions H:(0.7,0.3), C:(0.4,0.6) in H,C order, and emissions H:(0.2,0.4,0.4), C:(0.5,0.4,0.1) for observations 1,2,3. Find the most likely hidden path for observations 1,3,1 using Viterbi.
Given
Initial probabilities: π(H)=0.8, π(C)=0.2. Transition matrix: H→H=0.7, H→C=0.3, C→H=0.4, C→C=0.6. Emissions for labels (1,2,3): H=(0.2,0.4,0.4), C=(0.5,0.4,0.1). There is no END-state factor.
To find
The best hidden-state sequence and its joint score.
Formula and why it applies
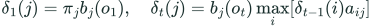 LaTeX:
\delta_1(j)=\pi_jb_j(o_1),\quad\delta_t(j)=b_j(o_t)\max_i[\delta_{t-1}(i)a_{ij}]Viterbi keeps two best prefix scores per column, one ending H and one ending C.
Solution
Step 1. Initialize at observation 1
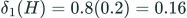 LaTeX:
\delta_1(H)=0.8(0.2)=0.16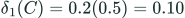 LaTeX:
\delta_1(C)=0.2(0.5)=0.10Step 2. At observation 3, calculate the H cell
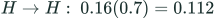 LaTeX:
H\to H:\ 0.16(0.7)=0.112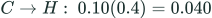 LaTeX:
C\to H:\ 0.10(0.4)=0.040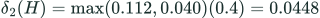 LaTeX:
\delta_2(H)=\max(0.112,0.040)(0.4)=0.0448Backpointer for this H cell: H.
Step 3. At observation 3, calculate the C cell
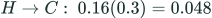 LaTeX:
H\to C:\ 0.16(0.3)=0.048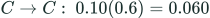 LaTeX:
C\to C:\ 0.10(0.6)=0.060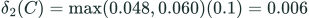 LaTeX:
\delta_2(C)=\max(0.048,0.060)(0.1)=0.006Backpointer for this C cell: C.
Step 4. At final observation 1, calculate H
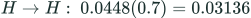 LaTeX:
H\to H:\ 0.0448(0.7)=0.03136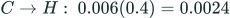 LaTeX:
C\to H:\ 0.006(0.4)=0.0024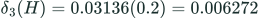 LaTeX:
\delta_3(H)=0.03136(0.2)=0.006272Backpointer: H.
Step 5. At final observation 1, calculate C
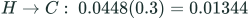 LaTeX:
H\to C:\ 0.0448(0.3)=0.01344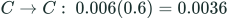 LaTeX:
C\to C:\ 0.006(0.6)=0.0036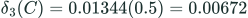 LaTeX:
\delta_3(C)=0.01344(0.5)=0.00672Backpointer: H.
Step 6. Select the final state
0.00672 > 0.006272, so the best final state is C.
Step 7. Trace back
Final C came from H at position2. That H came from H at position1. Reading forward gives H,H,C.
Step 8. Verify the recovered complete path
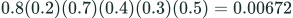 LaTeX:
0.8(0.2)(0.7)(0.4)(0.3)(0.5)=0.00672Question. For π(H)=0.8, π(C)=0.2; transitions H:(0.7,0.3), C:(0.4,0.6); emissions H:(0.2,0.4,0.4), C:(0.5,0.4,0.1) for labels1,2,3, decode observations 3,1.
Given
Initial probabilities: π(H)=0.8, π(C)=0.2. Transition matrix: H→H=0.7, H→C=0.3, C→H=0.4, C→C=0.6. Emissions for labels (1,2,3): H=(0.2,0.4,0.4), C=(0.5,0.4,0.1). There is no END-state factor.
To find
Best two-state hidden path and score.
Formula and why it applies
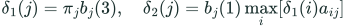 LaTeX:
\delta_1(j)=\pi_jb_j(3),\quad\delta_2(j)=b_j(1)\max_i[\delta_1(i)a_{ij}]The same recurrence applies even though the observation order changed.
Solution
Step 1. Initialize observation 3
 LaTeX:
\delta_1(H)=0.8(0.4)=0.32,\quad\delta_1(C)=0.2(0.1)=0.02Step 2. Calculate the final H
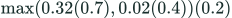 LaTeX:
\max(0.32(0.7),0.02(0.4))(0.2)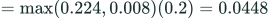 LaTeX:
=\max(0.224,0.008)(0.2)=0.0448Winning predecessor H.
Step 3. Calculate the final C
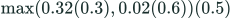 LaTeX:
\max(0.32(0.3),0.02(0.6))(0.5)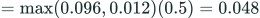 LaTeX:
=\max(0.096,0.012)(0.5)=0.048Winning predecessor H.
Step 4. Select and trace
Final C wins with 0.048 and came from H. The path is H,C.
Question. For π(H)=0.8, π(C)=0.2; transitions H:(0.7,0.3), C:(0.4,0.6); emissions H:(0.2,0.4,0.4), C:(0.5,0.4,0.1) for labels1,2,3, decode observations 2,2.
Given
Initial probabilities: π(H)=0.8, π(C)=0.2. Transition matrix: H→H=0.7, H→C=0.3, C→H=0.4, C→C=0.6. Emissions for labels (1,2,3): H=(0.2,0.4,0.4), C=(0.5,0.4,0.1). There is no END-state factor.
To find
Best path and score.
Formula and why it applies
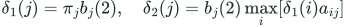 LaTeX:
\delta_1(j)=\pi_jb_j(2),\quad\delta_2(j)=b_j(2)\max_i[\delta_1(i)a_{ij}]Both states emit2 with probability 0.4, but their initial and transition probabilities still differ.
Solution
Step 1. Initialize
 LaTeX:
\delta_1(H)=0.8(0.4)=0.32,\quad\delta_1(C)=0.2(0.4)=0.08Step 2. Final H
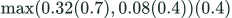 LaTeX:
\max(0.32(0.7),0.08(0.4))(0.4)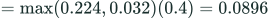 LaTeX:
=\max(0.224,0.032)(0.4)=0.0896Predecessor H.
Step 3. Final C
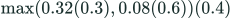 LaTeX:
\max(0.32(0.3),0.08(0.6))(0.4)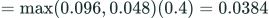 LaTeX:
=\max(0.096,0.048)(0.4)=0.0384Predecessor H.
Step 4. Select and trace
The final H score 0.0896 is larger. Its predecessor is H.
Yaad rakho: Har destination ke liye incoming paths compare; winner ka arrow yaad.