Natural Language Processing · M2 · read
Collocations and the purpose of a language model
N-grams and language models
Unit 3, pages 62–108; essential probability revision
A collocation is a conventional word combination whose words occur together more strongly than ordinary chance or independent frequencies would suggest. Examples include “strong tea”, “heavy rain” and “red wine”. A bigram is merely two consecutive items; it need not be a collocation. “of the” can be frequent because both words are frequent, while a collocation expresses a particularly strong association.
| Term | What it represents | Example |
|---|---|---|
| Bigram | Any adjacent two-token sequence | the book |
| Collocation | A characteristic strongly associated expression | heavy rain |
| Language model | A distribution used to score or predict sequences | P(rain | heavy) |
Definition. A statistical language model assigns a probability to a sequence of words, or equivalently predicts the next word from preceding context. It is useful for autocomplete, speech recognition, machine translation, spelling correction, assistive communication and ranking candidate text. High probability reflects patterns learned from its training distribution; it is not a guarantee of truth or grammatical correctness.
Noisy-channel connection. Suppose x is the observed noisy text or speech and y is a candidate intended message. The noisy-channel approach chooses the y that maximizes P(x | y)P(y). The channel model P(x | y) asks how y could produce x; the language model P(y) asks whether y is a plausible message. P(x) is the same for all candidate y and therefore can be omitted when ranking.
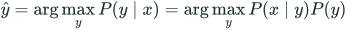 LaTeX:
\hat y=\arg\max_y P(y\mid x)=\arg\max_y P(x\mid y)P(y)Question. A spelling-correction system considers “flowers” and “flours”. For the observed input, the channel likelihoods are 0.2 and 0.4, and the respective language-model probabilities in context are 0.08 and 0.01. Which candidate does the noisy-channel rule choose?
Given
Candidate flowers: P(x|flowers)=0.2, P(flowers)=0.08. Candidate flours: P(x|flours)=0.4, P(flours)=0.01.
To find
The larger unnormalized candidate score.
Formula and why it applies
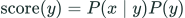 LaTeX:
\operatorname{score}(y)=P(x\mid y)P(y)Both the error mechanism and the language context matter. The same denominator would normalize both candidates.
Solution
Step 1. Score flowers
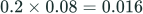 LaTeX:
0.2\times0.08=0.016Step 2. Score flours
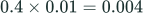 LaTeX:
0.4\times0.01=0.004Step 3. Compare
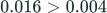 LaTeX:
0.016>0.004Yaad rakho: Har word-pair bigram hai; har frequent pair meaningful collocation nahi.
NLP M2 03: N-grams & Unigrams
- id
- nlp-m2-03-ngrams-language-models
- title
- NLP M2 03: N-grams & Unigrams
- title_confirmed
- true
- topic_title
- N-grams, chain rule and unigram models
- mode
- m2
- kind
- focused
- status
- available
- duration
- 9:52
- reviewed
- false
- notebook_url
- https://notebook.google.com/notebook/a270ef1e-c285-4d31-9db1-302090c5f8b1
- youtube_url
- corrected_visuals
- false
- upload_pending_correction
- false
- correction_note
- related_topic_ids
These are recorded generation statuses, not a live service check. Private YouTube and signed-in NotebookLM links require the owner's account. This export publishes existing catalog metadata, not private video files or an invented transcript.
NLP M2 — N-grams and Laplace | Reviewed worked numericals
- id
- overview-ngrams-laplace
- title
- NLP M2 — N-grams and Laplace | Reviewed worked numericals
- title_confirmed
- true
- topic_title
- NLP M2: N-Grams & Laplace
- mode
- m2
- kind
- supplemental
- status
- available
- duration
- 7:41
- reviewed
- true
- notebook_url
- https://notebook.google.com/notebook/a270ef1e-c285-4d31-9db1-302090c5f8b1
- youtube_url
- https://www.youtube.com/watch?v=RyPi8xq8ugU
- corrected_visuals
- true
- upload_pending_correction
- false
- correction_note
- Complete counts and four Laplace factors; corrected formulas, conditional-factor wording and rounding. Full transcript and detected slides checked; short voice corrections included.
- related_topic_ids
- nlp-m2-03-ngrams-language-models
- nlp-m2-04-bigram-trigram-tables
- nlp-m2-05-laplace-smoothing-discount
These are recorded generation statuses, not a live service check. Private YouTube and signed-in NotebookLM links require the owner's account. This export publishes existing catalog metadata, not private video files or an invented transcript.