Natural Language Processing · TEE · formulas
Spelling correction and edit distance
Application calculations
Formulas explained through full worked examples
Spelling correction proposes the intended word or sentence when the observed text contains an error. A non-word error produces an invalid vocabulary item (“recieve”); a real-word error produces an existing word in the wrong context (“I will meat you”). Dictionary lookup can detect many non-words but cannot reliably detect real-word errors.
Minimum edit distance
Levenshtein distance is the minimum total cost of insertions, deletions and substitutions needed to transform one string into another. In the examples below, each edit costs 1; matching characters cost 0. Transposition is not a single Levenshtein operation. State different costs explicitly if the question gives them.
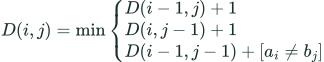 LaTeX:
D(i,j)=\min\begin{cases}D(i-1,j)+1\\D(i,j-1)+1\\D(i-1,j-1)+[a_i\ne b_j]\end{cases}Rows represent prefixes of the source; columns represent prefixes of the target. D(i,j) is the best cost for transforming the first i source characters to the first j target characters. Initialise D(i,0)=i and D(0,j)=j. The three choices are deletion, insertion and diagonal match/substitution.
Example 1 · cat → cut
Calculate the unit-cost Levenshtein distance from “cat” to “cut”. Show the dynamic-programming table.
Source=cat; target=cut; insertion=deletion=substitution=1; match=0.
To findMinimum edit cost.
Formula and why it applies
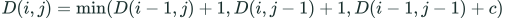 LaTeX:
D(i,j)=\min(D(i-1,j)+1,D(i,j-1)+1,D(i-1,j-1)+c)c = 0 for matching characters, 1 otherwise. Compare all three possible ways to reach each cell.
Solution
Step 1. Initialise empty prefixes
First row counts insertions; first column counts deletions.
Step 2. Fill row 1: source character “c”
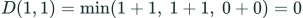 LaTeX:
D(1,1)=\min(1+1,\ 1+1,\ 0+0)=0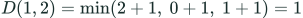 LaTeX:
D(1,2)=\min(2+1,\ 0+1,\ 1+1)=1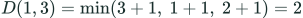 LaTeX:
D(1,3)=\min(3+1,\ 1+1,\ 2+1)=2Step 3. Fill row 2: source character “a”
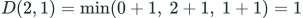 LaTeX:
D(2,1)=\min(0+1,\ 2+1,\ 1+1)=1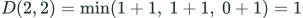 LaTeX:
D(2,2)=\min(1+1,\ 1+1,\ 0+1)=1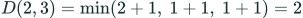 LaTeX:
D(2,3)=\min(2+1,\ 1+1,\ 1+1)=2Step 4. Fill row 3: source character “t”
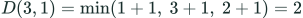 LaTeX:
D(3,1)=\min(1+1,\ 3+1,\ 2+1)=2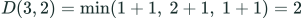 LaTeX:
D(3,2)=\min(1+1,\ 2+1,\ 1+1)=2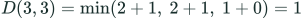 LaTeX:
D(3,3)=\min(2+1,\ 2+1,\ 1+0)=1Step 5. Read the completed matrix
| Source / target | ∅ | c | u | t |
|---|---|---|---|---|
| ∅ | 0 | 1 | 2 | 3 |
| c | 1 | 0 | 1 | 2 |
| a | 2 | 1 | 1 | 2 |
| t | 3 | 2 | 2 | 1 |
Example 2 · at → cat
Calculate the unit-cost Levenshtein distance from “at” to “cat”. Show the dynamic-programming table.
Source=at; target=cat; insertion=deletion=substitution=1; match=0.
To findMinimum edit cost.
Formula and why it applies
LaTeX: D(i,j)=\min(D(i-1,j)+1,D(i,j-1)+1,D(i-1,j-1)+c)c = 0 for matching characters, 1 otherwise. Compare all three possible ways to reach each cell.
Solution
Step 1. Initialise empty prefixes
First row counts insertions; first column counts deletions.
Step 2. Fill row 1: source character “a”
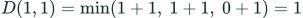 LaTeX:
D(1,1)=\min(1+1,\ 1+1,\ 0+1)=1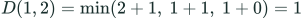 LaTeX:
D(1,2)=\min(2+1,\ 1+1,\ 1+0)=1LaTeX: D(1,3)=\min(3+1,\ 1+1,\ 2+1)=2Step 3. Fill row 2: source character “t”
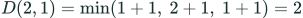 LaTeX:
D(2,1)=\min(1+1,\ 2+1,\ 1+1)=2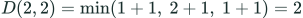 LaTeX:
D(2,2)=\min(1+1,\ 2+1,\ 1+1)=2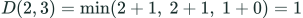 LaTeX:
D(2,3)=\min(2+1,\ 2+1,\ 1+0)=1Step 4. Read the completed matrix
| Source / target | ∅ | c | a | t |
|---|---|---|---|---|
| ∅ | 0 | 1 | 2 | 3 |
| a | 1 | 1 | 1 | 2 |
| t | 2 | 2 | 2 | 1 |
Example 3 · cats → cat
Calculate the unit-cost Levenshtein distance from “cats” to “cat”. Show the dynamic-programming table.
Source=cats; target=cat; insertion=deletion=substitution=1; match=0.
To findMinimum edit cost.
Formula and why it applies
LaTeX: D(i,j)=\min(D(i-1,j)+1,D(i,j-1)+1,D(i-1,j-1)+c)c = 0 for matching characters, 1 otherwise. Compare all three possible ways to reach each cell.
Solution
Step 1. Initialise empty prefixes
First row counts insertions; first column counts deletions.
Step 2. Fill row 1: source character “c”
LaTeX: D(1,1)=\min(1+1,\ 1+1,\ 0+0)=0LaTeX: D(1,2)=\min(2+1,\ 0+1,\ 1+1)=1LaTeX: D(1,3)=\min(3+1,\ 1+1,\ 2+1)=2Step 3. Fill row 2: source character “a”
LaTeX: D(2,1)=\min(0+1,\ 2+1,\ 1+1)=1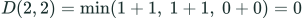 LaTeX:
D(2,2)=\min(1+1,\ 1+1,\ 0+0)=0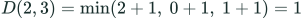 LaTeX:
D(2,3)=\min(2+1,\ 0+1,\ 1+1)=1Step 4. Fill row 3: source character “t”
LaTeX: D(3,1)=\min(1+1,\ 3+1,\ 2+1)=2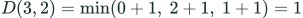 LaTeX:
D(3,2)=\min(0+1,\ 2+1,\ 1+1)=1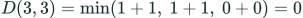 LaTeX:
D(3,3)=\min(1+1,\ 1+1,\ 0+0)=0Step 5. Fill row 4: source character “s”
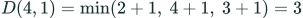 LaTeX:
D(4,1)=\min(2+1,\ 4+1,\ 3+1)=3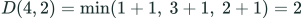 LaTeX:
D(4,2)=\min(1+1,\ 3+1,\ 2+1)=2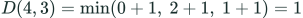 LaTeX:
D(4,3)=\min(0+1,\ 2+1,\ 1+1)=1Step 6. Read the completed matrix
| Source / target | ∅ | c | a | t |
|---|---|---|---|---|
| ∅ | 0 | 1 | 2 | 3 |
| c | 1 | 0 | 1 | 2 |
| a | 2 | 1 | 0 | 1 |
| t | 3 | 2 | 1 | 0 |
| s | 4 | 3 | 2 | 1 |
Noisy-channel correction
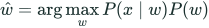 LaTeX:
\hat w=\arg\max_w P(x\mid w)P(w)x is the observed misspelling and w a candidate intended word. P(x | w) is the error-model likelihood; P(w) is the language-model prior. In context, replace the isolated-word prior with an appropriate contextual probability. A frequent word with a plausible typo may beat a rarer candidate, but context can reverse the ranking.
Candidate ranking
For observed “teh”, candidate “the” has prior 0.05 and error likelihood 0.02. Candidate “ten” has prior 0.01 and likelihood 0.01. Select the intended word.
Two candidates and their prior/error-model likelihoods are supplied.
To findLargest noisy-channel score.
Formula and why it applies
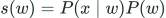 LaTeX:
s(w)=P(x\mid w)P(w)Multiply likelihood by prior; the same evidence normaliser is irrelevant to ranking.
Solution
Step 1. Score the
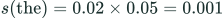 LaTeX:
s(\text{the})=0.02\times0.05=0.001Step 2. Score ten
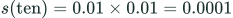 LaTeX:
s(\text{ten})=0.01\times0.01=0.0001Step 3. Compare
0.001 is ten times 0.0001.