Natural Language Processing · TEE · formulas
Unigrams, bigrams and trigrams: construct them correctly
N-grams & probability
Formulas explained through full worked examples
Definition. An n-gram is a contiguous sequence of n items. For word n-grams, the items are consecutive word tokens. A unigram contains one word; a bigram contains two; a trigram contains three. Character n-grams use characters instead, so always identify the unit being counted.
For m tokens without padding, the number of n-gram positions is max(0, m−n+1). Repeated positions may contain the same n-gram type. A bag-of-n-grams representation counts each n-gram type and loses the overall sentence order beyond the local order inside each n-gram.
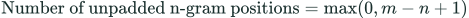 LaTeX:
\text{Number of unpadded n-gram positions}=\max(0,m-n+1)Question. List all word unigrams, bigrams and trigrams for “the prime minister of our country”. Do not add boundary tokens.
Given
Six tokens: the, prime, minister, of, our, country. n = 1, 2 and 3.
To find
All three lists and their counts.
Formula and why it applies
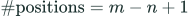 LaTeX:
\#\text{positions}=m-n+1Each window must contain consecutive words and move one position. No wraparound or invented final word is allowed.
Solution
Step 1. Take one word at a time
Unigrams: (the), (prime), (minister), (of), (our), (country). Count = 6−1+1 = 6.
Step 2. Take two consecutive words
Bigrams: (the, prime), (prime, minister), (minister, of), (of, our), (our, country). Count = 6−2+1 = 5.
Step 3. Take three consecutive words
Trigrams: (the, prime, minister), (prime, minister, of), (minister, of, our), (of, our, country). Count = 6−3+1 = 4.
Question. Construct bigrams for “I like tea” using one start and one end marker.
Given
Original tokens: I, like, tea. Add <s> and </s> once each.
To find
The boundary-aware bigram sequence.
Formula and why it applies
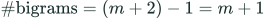 LaTeX:
\#\text{bigrams}=(m+2)-1=m+1The start context predicts the first word, and the last word predicts that the sentence ends.
Solution
Step 1. Write the padded sequence
<s> I like tea </s>
Step 2. Move a two-token window
(<s>, I), (I, like), (like, tea), (tea, </s>).
Step 3. Count the windows
 LaTeX:
3+1=4Question. Construct trigrams for “I like tea” using two start markers and one end marker.
Given
Original sentence has three words. For a trigram model each predicted token needs two prior context tokens.
To find
All trigram prediction events.
Formula and why it applies
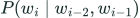 LaTeX:
P(w_i\mid w_{i-2},w_{i-1})Two start markers provide a complete context even for the first word.
Solution
Step 1. Pad with two starts
<s> <s> I like tea </s>
Step 2. Slide a three-token window
(<s>, <s>, I), (<s>, I, like), (I, like, tea), (like, tea, </s>).
Step 3. Count predicted events
The model predicts I, like, tea and the end marker: four predictions.
Question. Give the bag-of-bigrams counts for “a b a b” without padding.
Given
Four tokens in their given order.
To find
Bigram positions, distinct bigram types and their counts.
Formula and why it applies
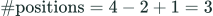 LaTeX:
\#\text{positions}=4-2+1=3A bag stores frequencies; repeated bigrams must not be discarded.
Solution
Step 1. Enumerate all positions
(a,b), (b,a), (a,b).
Step 2. Group identical pairs
| Bigram type | Count |
|---|---|
| a b | 2 |
| b a | 1 |
Yaad rakho: n-gram mein n words; context mein n−1 words.