Natural Language Processing · TEE · formulas
N-gram interpolation: weighted evidence from several histories
Faculty topics: interpolation and Stupid Backoff
Unit 3 PDF p147 names these methods. Neither supplied TEE paper asks their numerical calculation; the worked values below are authored examples.
Faculty topic; not an observed numerical PYQ. Unit 3 PDF p147 names these methods. Neither supplied TEE paper asks their numerical calculation; the worked values below are authored examples.
Interpolation combines several context lengths for every prediction. A trigram estimate is specific but may have little evidence. Bigram and unigram estimates use less context and can support unseen longer sequences. A weighted mixture combines their information.
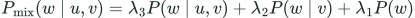 LaTeX:
P_{\mathrm{mix}}(w\mid u,v)=\lambda_3P(w\mid u,v)+\lambda_2P(w\mid v)+\lambda_1P(w)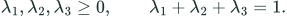 LaTeX:
\lambda_1,\lambda_2,\lambda_3\ge0,\qquad\lambda_1+\lambda_2+\lambda_3=1.Each component must be a normalized distribution over the same vocabulary. Then summing the mixture over all possible words gives λ₁+λ₂+λ₃=1. A zero higher-order count can be rescued by positive lower-order evidence. Unlike simple backoff, interpolation can combine all levels even when the trigram was seen.
Question. For predicting tea after I like, suppose trigram, bigram and unigram probabilities are 0, 0.2 and 0.1. Use weights λ₃=0.5, λ₂=0.3 and λ₁=0.2 to calculate the interpolated probability. Repeat for coffee with probabilities 0.4, 0.1 and 0.05. [Authored worked example]
Answer
Given
The three distributions use one vocabulary. Nonnegative weights sum to 1. These are supplied probabilities; no count estimation is needed.
To find
Pmix(tea | I,like) and Pmix(coffee | I,like).
Formula and why it applies
 LaTeX:
P_{mix}=\lambda_3P_3+\lambda_2P_2+\lambda_1P_1We add weighted alternatives from models, rather than multiply sequential word events.
Solution
Step 1. Check the weights
 LaTeX:
0.5+0.3+0.2=1.Step 2. Calculate the three tea contributions
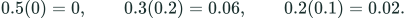 LaTeX:
0.5(0)=0,\qquad0.3(0.2)=0.06,\qquad0.2(0.1)=0.02.Step 3. Add the tea contributions
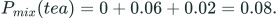 LaTeX:
P_{mix}(tea)=0+0.06+0.02=0.08.Step 4. Calculate the coffee contributions
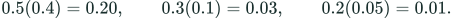 LaTeX:
0.5(0.4)=0.20,\qquad0.3(0.1)=0.03,\qquad0.2(0.05)=0.01.Step 5. Add and compare
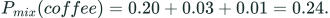 LaTeX:
P_{mix}(coffee)=0.20+0.03+0.01=0.24.Coffee gets three times tea’s probability in this model. Other vocabulary outcomes carry the remaining mass; these two displayed entries are not the whole distribution.
Yaad rakho: Interpolation = sab context-lengths ka weighted mix. Word-sequence product aur model-mixture sum alag operations hain.