Natural Language Processing · TEE · formulas
Backoff and the important score-versus-probability distinction
Faculty topics: interpolation and Stupid Backoff
Unit 3 PDF p147 names these methods. Neither supplied TEE paper asks their numerical calculation; the worked values below are authored examples.
Faculty topic; not an observed numerical PYQ. Unit 3 PDF p147 names these methods. Neither supplied TEE paper asks their numerical calculation; the worked values below are authored examples.
Backoff uses a shorter history when the longer-history estimate lacks evidence. A properly normalized backoff model discounts some seen-event probability and allocates the remaining mass across unseen continuations using lower-order probabilities and normalization factors.
Stupid Backoff is a specifically named efficient scoring method in the slides’ list. It uses an observed n-gram relative frequency when available; otherwise it multiplies the shorter-history score by a fixed penalty, commonly 0.4. Its output is generally an unnormalized score, not a conditional probability distribution. Do not insert raw Stupid Backoff scores into standard probability-based perplexity and call the result a normalized-model perplexity.
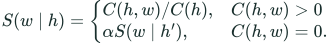 LaTeX:
S(w\mid h)=\begin{cases}C(h,w)/C(h),&C(h,w)>0\\ \alpha S(w\mid h'),&C(h,w)=0.\end{cases}Here h′ drops the oldest history word; α is the backoff penalty. At the unigram base, use C(w)/N. The letter α here is a penalty, not the forward-HMM variable introduced later.
Question. A bigram scorer has complete vocabulary {a,b}. After h, C(h,a)=2 and C(h,b)=0. The unigram probabilities are P(a)=P(b)=0.5. Apply Stupid Backoff with penalty 0.4 and show whether the scores form a normalized row. [Authored worked example]
Answer
Given
C(h)=2. The a bigram is observed; the b bigram is unseen. Unigram probabilities are supplied.
To find
S(a|h), S(b|h), their sum, and whether they are probabilities.
Formula and why it applies
Use relative frequency for an observed pair and α times the unigram base for an unseen pair. The method does not discount a’s observed score in this example.
Solution
Step 1. Score the observed pair
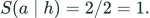 LaTeX:
S(a\mid h)=2/2=1.Step 2. Back off for the unseen pair
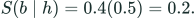 LaTeX:
S(b\mid h)=0.4(0.5)=0.2.Step 3. Add the complete row
 LaTeX:
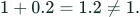
1+0.2=1.2\ne1.Step 4. Interpret the failure of normalization
The scores can rank a above b, but the raw row cannot be called a probability distribution. Merely labelling the method “smoothing” does not change this.
| Method | Operation | Normalization |
|---|---|---|
| Add-one/add-k | Adjust all allowed outcome counts and the total | Normalized with a fixed vocabulary |
| Interpolation | Mix normalized distributions using nonnegative weights summing to 1 | Normalized |
| Normalized backoff | Discount seen events and distribute remaining mass over unseen events | Normalized when its factors are correctly computed |
| Stupid Backoff | Keep seen relative frequencies; penalize shorter-history scores for unseen n-grams | Generally not normalized |
Scope: Unit 3 slide 147 lists Stupid Backoff and n-gram interpolation; the class calculations emphasize Laplace. These short worked extensions explain the listed methods without claiming extra official exam weight.