Natural Language Processing · TEE · formulas
Bag of words and bag of n-grams
Representation & similarity
Formulas explained through full worked examples
Bag of words (BoW) represents a document by the counts of vocabulary terms, discarding their positions. A binary BoW variant stores only presence/absence; a count BoW stores frequencies. State which is used.
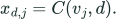 LaTeX:
x_{d,j}=C(v_j,d). LaTeX:
x_{d,j} is document  LaTeX:
d's coordinate for vocabulary term  LaTeX:
v_j.  LaTeX:
C(v_j,d) is its occurrence count.
A bag of n-grams uses short contiguous token sequences as features. Bigrams can distinguish “not good” from “good”, but increasing n enlarges the vocabulary and creates more rare features.
Question. Build count and binary BoW for D1=“cat cat dog” and D2=“dog fish”. Use vocabulary [cat,dog,fish] and no stopword removal.
Given
Two tokenized documents, fixed vocabulary order.
To find
Count vectors and binary vectors.
Formula and why it applies
Count BoW uses LaTeX: C(v_j,d). Binary BoW is 1 when that count is positive and 0 otherwise.
Step 1. D1 counts
cat=2, dog=1, fish=0 → [2,1,0].
Step 2. D2 counts
cat=0, dog=1, fish=1 → [0,1,1].
Step 3. Convert to presence
D1 [1,1,0]; D2 [0,1,1].
Answer. Count rows [2,1,0], [0,1,1]; binary rows [1,1,0], [0,1,1].
Question. After lowercasing and removing {is,a,means}, obtain BoW vectors for D1=“Continuous learning is learning lifetime”, D2=“Continuous learning means lifetime learning”, D3=“Learning is a good practice”. Use [continuous,good,learning,lifetime,practice].
Given
Three documents and exact stopword set from the supplied slides.
To find
The document–term count matrix.
Formula and why it applies
Remove only the listed stopwords, then count every remaining token in the fixed column order.
Step 1. Clean D1
[continuous,learning,learning,lifetime] → [1,0,2,1,0].
Step 2. Clean D2
[continuous,learning,lifetime,learning] → [1,0,2,1,0].
Step 3. Clean D3
[learning,good,practice] → [0,1,1,0,1].
Step 4. Compare D1 and D2
They have identical BoW vectors despite different original wording/order.
Answer. Rows [1,0,2,1,0], [1,0,2,1,0], [0,1,1,0,1].
Question. Build a bag of bigrams for “not good but not bad” with vocabulary [not good,good but,but not,not bad]. Do not add sentence boundary tokens.
Given
Five tokens; use adjacent pairs, stride 1.
To find
The bigram count vector.
Formula and why it applies
A sequence of  LaTeX:
L tokens has  LaTeX:
L-1 adjacent bigrams when no boundaries are added.
Step 1. Enumerate pairs
(not,good), (good,but), (but,not), (not,bad).
Step 2. Count each vocabulary bigram
Each appears once.
Step 3. Write vector
[1,1,1,1].
Answer. Four bigram features, each with count 1.
BoW: order bhool, word-count rakh. Bag of bigrams: neighbouring word-pair count.