Natural Language Processing · TEE · formulas
Label and one-hot encoding: three complete examples
Representation & similarity
Formulas explained through full worked examples
Label encoding assigns each category or word a unique integer ID. One-hot encoding assigns a length- LaTeX:
V vector with one 1 at the word's vocabulary position and zeros elsewhere.
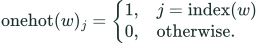 LaTeX:
\operatorname{onehot}(w)_j=\begin{cases}1,&j=\operatorname{index}(w)\\0,&\text{otherwise.}\end{cases}The index is an ID, not a meaning score. One-hot represents one token/category; a multiword document generally needs multiple token vectors or an aggregation scheme.
Question. Encode “dog cat dog” using vocabulary [cat,dog,fish], IDs starting at 0. Give label IDs and a one-hot vector for every token.
Given
cat→0, dog→1, fish→2. Vector columns have the same order.
To find
The ID sequence and three one-hot rows.
Formula and why it applies
Replace each word by its ID for labels; set its vocabulary position to 1 for one-hot.
Step 1. Label IDs
dog→1, cat→0, dog→1 → [1,0,1].
Step 2. First dog
[0,1,0].
Step 3. Cat
[1,0,0].
Step 4. Second dog
[0,1,0]. Repeated tokens keep the same representation.
Answer. IDs [1,0,1]; one-hot rows [0,1,0], [1,0,0], [0,1,0].
Question. Encode the city sequence Mumbai, Delhi, Mumbai, Pune using vocabulary [Delhi,Mumbai,Pune] and label IDs starting at 1.
Given
Delhi→1, Mumbai→2, Pune→3.
To find
IDs and one-hot rows.
Formula and why it applies
One-hot uses three coordinates regardless of whether label IDs begin at 0 or 1.
Step 1. IDs
[2,1,2,3].
Step 2. Mumbai rows
Each Mumbai → [0,1,0].
Step 3. Delhi and Pune
Delhi→[1,0,0]; Pune→[0,0,1].
Answer. Rows [0,1,0], [1,0,0], [0,1,0], [0,0,1].
Question. One-hot encode categories [red,green,blue] for a linear regression with an intercept. Then give dummy coding after dropping blue.
Given
Full column order [red,green,blue]. Blue is the baseline.
To find
Full and reduced codes.
Formula and why it applies
Full one-hot rows sum to 1. With an intercept this creates a linear dependency; dropping one category column gives k−1 independent dummy indicators.
Step 1. Full encoding
| Category | red | green | blue |
|---|---|---|---|
| red | 1 | 0 | 0 |
| green | 0 | 1 | 0 |
| blue | 0 | 0 | 1 |
Step 2. Drop blue column
| Category | red | green |
|---|---|---|
| red | 1 | 0 |
| green | 0 | 1 |
| blue | 0 | 0 |
Step 3. Interpret zero row
[0,0] now identifies the baseline blue, not missing data.
Answer. Full width 3; reduced dummy width 2. Dropping a column is model-dependent, not a requirement for every neural embedding input.
Limitations: one-hot is large and sparse and does not express semantic similarity. Unseen words need a defined unknown-token or vocabulary-update policy. Label IDs are compact but should not be treated as an ordered scalar feature for nominal words.
Label = ID number. One-hot = us ID ke box mein 1, baaki 0.