Natural Language Processing · TEE · formulas
Distributional hypothesis and a co-occurrence matrix
Representation & similarity
Formulas explained through full worked examples
The distributional hypothesis states that words occurring in similar contexts tend to have similar meanings or semantic behaviour. “Cat” and “dog” often occur near pet, feed and animal. Their context patterns can therefore be represented and compared numerically.
A vector is an ordered list of numbers. Each position must have a fixed meaning. For context order [pet, food, road], cat=[4,3,0] means four co-occurrences with pet, three with food, none with road. A matrix stacks vectors as rows in a table.
A word–context co-occurrence matrix records how often a target word occurs with each context word under a specified context definition. A window may be a sentence, document, or a fixed number of neighbouring tokens. State its width, direction and whether targets count themselves.
Question. Build the symmetric co-occurrence matrix for “cats eat fish” using a window of one token on either side, no self-counts and vocabulary [cats,eat,fish].
Given
One sentence, one occurrence of each token. Left and right adjacent tokens are contexts.
To find
A 3×3 target-by-context count matrix.
Formula and why it applies
 LaTeX:
X_{ij} counts the number of times context word  LaTeX:
j occurs within the chosen window of target  LaTeX:
i.
Step 1. Target cats
Only eat is adjacent. Row cats = [0,1,0].
Step 2. Target eat
cats is left and fish is right. Row eat = [1,0,1].
Step 3. Target fish
Only eat is adjacent. Row fish = [0,1,0].
Step 4. Assemble the matrix
| Target / context | cats | eat | fish |
|---|---|---|---|
| cats | 0 | 1 | 0 |
| eat | 1 | 0 | 1 |
| fish | 0 | 1 | 0 |
Answer. Rows are [0,1,0], [1,0,1], [0,1,0]. The symmetry follows from the symmetric window.
Question. Build a target–context matrix for sentences “cats eat fish” and “dogs eat fish”. Target words are cats and dogs; context columns [eat,fish]; use the entire sentence excluding the target.
Given
Each sentence contains one target. Count context token occurrences.
To find
Two context vectors.
Formula and why it applies
Count each context word in every sentence containing the target.
Step 1. Count cats contexts
In its sentence: eat occurs once, fish once → [1,1].
Step 2. Count dogs contexts
In its sentence: eat occurs once, fish once → [1,1].
Step 3. Compare
Both targets have identical observed context patterns in this very small corpus.
Answer. cats=[1,1], dogs=[1,1]. This corpus supplies no context evidence to distinguish them.
Question. For “a b a”, use a right-only window of one token. Build the matrix with rows/columns [a,b].
Given
Count directed target→next-word events, not both directions.
To find
The co-occurrence matrix.
Formula and why it applies
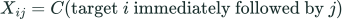 LaTeX:
X_{ij}=C(\text{target }i\text{ immediately followed by }j).
Step 1. First target a
Next token is b → add 1 to X(a,b).
Step 2. Target b
Next token is a → add 1 to X(b,a).
Step 3. Final a
No following token → no addition.
Step 4. Write matrix
| Target / next | a | b |
|---|---|---|
| a | 0 | 1 |
| b | 1 | 0 |
Answer. a=[0,1], b=[1,0]. A different context window would produce a different matrix.
Word ka meaning: uske aas-paas kaunse words kitni baar aaye, uski number-list.