Natural Language Processing · TEE · formulas
The GloVe objective and numerical interpretation
Representation & similarity
Formulas explained through full worked examples
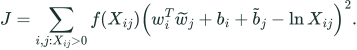 LaTeX:
J=\sum_{i,j:X_{ij}>0}f(X_{ij})\left(w_i^T\widetilde w_j+b_i+\widetilde b_j-\ln X_{ij}\right)^2.What each piece means:  LaTeX:
w_i is a target vector;  LaTeX:
\widetilde w_j is a separate context vector; the dot product estimates their compatibility; biases adjust word-level baselines. The desired score is the natural log of the observed count. Squaring penalizes both positive and negative errors. Weighting prevents unreliable rare pairs or extremely frequent pairs from dominating inappropriately.
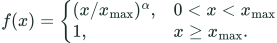 LaTeX:
f(x)=\begin{cases}(x/x_{\max})^\alpha,&0<x<x_{\max}\\1,&x\ge x_{\max}.\end{cases}The original commonly used settings are  LaTeX:
x_{\max}=100,  LaTeX:
\alpha=0.75. They are hyperparameters, not learned word embeddings. Zero-count pairs do not require evaluating  LaTeX:
\ln 0 in the displayed nonzero-count objective.
Question. For one nonzero GloVe pair, X=4, weighting f(X)=0.5, target vector [1,2], context vector [0.5,0], and both biases 0. Find its contribution to J.
Given
Use natural logarithm. Only one pair is being evaluated.
To find
Weighted squared residual.
Formula and why it applies
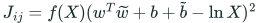 LaTeX:
J_{ij}=f(X)(w^T\widetilde w+b+\widetilde b-\ln X)^2.
Step 1. Dot product
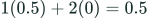 LaTeX:
1(0.5)+2(0)=0.5.
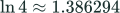
Step 2. Log-count target
 LaTeX:
\ln4\approx1.386294.
Step 3. Residual
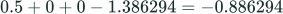 LaTeX:
0.5+0+0-1.386294=-0.886294.
Step 4. Square and weight
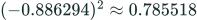 LaTeX:
(-0.886294)^2\approx0.785518. Multiply by 0.5 → approximately 0.392759.
Answer. The pair contributes approximately 0.392759 to the objective.
Question. A GloVe pair has X=e², weight 1, dot product 1.5 and biases 0.2 and 0.3. Calculate its objective contribution.
Given
Natural logarithm, so ln(e²)=2.
To find
The squared weighted error.
Formula and why it applies
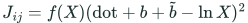 LaTeX:
J_{ij}=f(X)(\text{dot}+b+\widetilde b-\ln X)^2.
Step 1. Predicted score
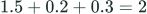 LaTeX:
1.5+0.2+0.3=2.
Step 2. Target score
 LaTeX:
\ln(e^2)=2.
Step 3. Residual and square
 LaTeX:
2-2=0;  LaTeX:
1\times0^2=0.
Answer. Contribution 0: this pair is fitted exactly.
Question. Use xmax=100 and α=0.75. A GloVe pair has X=16 and residual 2. Find its weighting and loss contribution.
Given
16 is below xmax, so use the power branch.
To find
f(16) and weighted squared residual.
Formula and why it applies
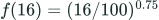 LaTeX:
f(16)=(16/100)^{0.75}, and 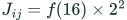 LaTeX:
J_{ij}=f(16)\times2^2.
Step 1. Ratio
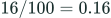 LaTeX:
16/100=0.16.
Step 2. Power
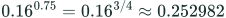 LaTeX:
0.16^{0.75}=0.16^{3/4}\approx0.252982.
Step 3. Square residual
 LaTeX:
2^2=4.
Step 4. Multiply
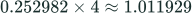 LaTeX:
0.252982\times4\approx1.011929.
Answer. f≈0.252982 and contribution≈1.011929.
Six steps to explain the algorithm
- Collect a corpus and choose a context window.
- Build the global co-occurrence matrix.
- Study row-normalized context probabilities and their ratios.
- Define the weighted log-count fitting objective.
- Optimize word/context vectors and biases.
- Use the learned embeddings for similarity, analogy or downstream tasks.
GloVe: global counts → log target → dot product prediction → weighted squared error kam karo.