Natural Language Processing · TEE · mocks
Q5A · TF–IDF matrix
Timed practice · Solved final paper · December 2025
TEE · actual previous paper · 100 marks · 180 minutes
Sentence A: “The student read a science book in the library”
Sentence B: “The teacher read a history book in the classroom”
1. Construct the TF-IDF matrix for these sentences after removing the stop words {The, a, in}.
2. Identify and comment on the important terms in each sentence based on their TF-IDF scores. [10 marks]
Answer
Given
Two documents, N = 2. Remove the listed stop words case-insensitively, so both “The” and “the” are removed. Use raw count TF and natural-log IDF, the convention used in the course key.
To find
The term-by-document TF–IDF matrix and the terms that distinguish each sentence.
Formula: which one and why
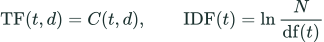 LaTeX:
\mathrm{TF}(t,d)=C(t,d),\qquad \mathrm{IDF}(t)=\ln\frac{N}{\mathrm{df}(t)}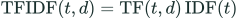 LaTeX:
\mathrm{TFIDF}(t,d)=\mathrm{TF}(t,d)\,\mathrm{IDF}(t)C(t,d) is the number of occurrences of term t in document d. df(t) is the number of documents containing t, not its total token count. N is the number of documents. IDF downweights terms shared by many documents.
Solution
Step 1. Clean and list the tokens
A: student, read, science, book, library.
B: teacher, read, history, book, classroom. Each retained token appears once in its sentence.
Step 2. Fix one common vocabulary order
student, read, science, book, library, teacher, history, classroom. Each row must refer to the same term in both documents.
Step 3. Count document frequency and calculate IDF
| Term type | df | IDF calculation |
|---|---|---|
| read, book | 2 | ln(2/2) = ln(1) = 0 |
| Every other term | 1 | ln(2/1) = ln(2) ≈ 0.693147 |
A term absent from a document has TF = 0. A present term has TF = 1 here.
Step 4. Multiply TF by IDF
| Term | TF in A | TF in B | IDF | TF–IDF A | TF–IDF B |
|---|---|---|---|---|---|
| student | 1 | 0 | 0.693147 | 0.693147 | 0 |
| read | 1 | 1 | 0 | 0 | 0 |
| science | 1 | 0 | 0.693147 | 0.693147 | 0 |
| book | 1 | 1 | 0 | 0 | 0 |
| library | 1 | 0 | 0.693147 | 0.693147 | 0 |
| teacher | 0 | 1 | 0.693147 | 0 | 0.693147 |
| history | 0 | 1 | 0.693147 | 0 | 0.693147 |
| classroom | 0 | 1 | 0.693147 | 0 | 0.693147 |
Step 5. Interpret the weights
A is distinguished by student, science and library. B is distinguished by teacher, history and classroom. “read” and “book” have zero IDF in this tiny unsmoothed two-document collection because they appear in every document; that does not mean those words are meaningless in English.
Final answer
All six document-specific terms receive 0.693147 in their own document and 0 in the other. Shared read and book receive 0 in both.
Yaad rakho: TF: is document mein kitni baar? IDF: kitne documents mein common? Rare-across-documents term ko zyada weight.
If normalized TF is explicitly requested, divide each present-token count by five; each nonzero weight becomes 0.693147/5 = 0.1386294. Do not silently switch conventions.