Natural Language Processing · TEE · mocks
Q5A · Why TF–IDF is useful
Timed practice · Solved re-exam · February 2026
TEE · actual previous paper · 100 marks · 180 minutes
Answer
TF–IDF represents each document using weights that combine within-document term frequency with how unusual a term is across the collection. It supports information retrieval by giving larger weight to terms that are frequent in a document but not present in every document.
Given
Use three short documents: D₁ = “solar energy solar”; D₂ = “wind energy”; D₃ = “energy policy”. Use raw-count TF and natural-log unsmoothed IDF. N = 3.
To find
A TF–IDF representation illustrating why distinctive terms help retrieve relevant documents.
Formula: which one and why
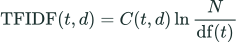 LaTeX:
\mathrm{TFIDF}(t,d)=C(t,d)\ln\frac{N}{\mathrm{df}(t)}C counts occurrences within a document; df counts documents containing the term. The logarithm reduces the scale of very large rarity ratios.
Solution
Step 1. Count term occurrences
| Term | D₁ | D₂ | D₃ | df |
|---|---|---|---|---|
| solar | 2 | 0 | 0 | 1 |
| energy | 1 | 1 | 1 | 3 |
| wind | 0 | 1 | 0 | 1 |
| policy | 0 | 0 | 1 | 1 |
Step 2. Calculate IDF
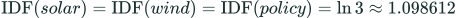 LaTeX:
\mathrm{IDF}(solar)=\mathrm{IDF}(wind)=\mathrm{IDF}(policy)=\ln3\approx1.098612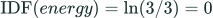 LaTeX:
\mathrm{IDF}(energy)=\ln(3/3)=0Step 3. Multiply each count by its IDF
| Term | D₁ weight | D₂ weight | D₃ weight |
|---|---|---|---|
| solar | 2 × 1.098612 = 2.197224 | 0 | 0 |
| energy | 0 | 0 | 0 |
| wind | 0 | 1.098612 | 0 |
| policy | 0 | 0 | 1.098612 |
Step 4. Connect the representation to retrieval
A query containing “solar” matches D₁’s high solar coordinate. A query containing “wind” matches D₂. “energy” alone cannot distinguish these documents under this unsmoothed collection because it occurs in all three. A retrieval system can compare query and document vectors, commonly by cosine similarity.
Final answer
TF–IDF preserves distinctive lexical evidence and reduces dominance by collection-wide frequent terms. D₁ is most relevant to a solar query under these features.
Yaad rakho: Document mein frequent + collection mein rare = high TF–IDF.
Strengths and limits
The representation is sparse, interpretable and useful as a fast baseline. However, basic TF–IDF ignores word order and does not recognise synonyms or multiple word senses automatically. Its weights depend on the collection and on the chosen TF/IDF convention. Fit IDF on training or indexed documents, not on a hidden test set.