Natural Language Processing · TEE · papers
Q2a · CBOW and Skip-gram architecture
2022-11-22 · final · recovered AI paper
Previous examination · complete worked answers
Answer
Word2Vec learns dense word embeddings by predicting words from nearby context. Its two common architectures are CBOW and skip-gram. A vocabulary ID or one-hot vector is the input representation; the learned embedding table converts that identity into a short trainable vector.
| Architecture | Input | Prediction | Memory cue |
|---|---|---|---|
| CBOW | Surrounding context words | Centre/target word | Context → centre |
| Skip-gram | Centre/target word | Surrounding words | Centre → context |
For vocabulary size  LaTeX:
V and embedding dimension  LaTeX:
d, an input one-hot row is  LaTeX:
1\times V; the input embedding matrix is  LaTeX:
V\times d; the hidden row is  LaTeX:
1\times d; the output matrix is  LaTeX:
d\times V; output scores are LaTeX: 1\times V. Multiplying a one-hot row by the embedding matrix simply selects one row.
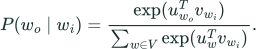 LaTeX:
P(w_o\mid w_i)=\frac{\exp(u_{w_o}^{T}v_{w_i})}{\sum_{w\in V}\exp(u_w^{T}v_{w_i})}. LaTeX:
v_{w_i} is the input word embedding,  LaTeX:
u_w an output-context embedding, and the dot product is a compatibility score. Softmax turns all scores into probabilities that sum to one. Training increases the probability of observed context words. Negative sampling or hierarchical softmax can reduce computation in larger vocabularies; use the algorithm specified by the question.
Question. For the sentence “the cat sat on mat”, generate CBOW and skip-gram training data for centre word sat with a window of one token on each side.
Given
Tokens indexed 1 to 5: the, cat, sat, on, mat. Centre = sat.
To find
The CBOW example and the skip-gram pairs.
Formula and why it applies
CBOW predicts the centre from its neighbours; skip-gram predicts each neighbour from the centre.
Step 1. Identify neighbours
Left neighbour = cat; right neighbour = on. “the” and “mat” are outside this window.
Step 2. CBOW example
Input [cat,on] → target sat.
Step 3. Skip-gram examples
(sat,cat) and (sat,on), with first item as input and second as predicted context.
Answer. CBOW: [cat,on]→sat. Skip-gram: sat→cat and sat→on.
Question. The embeddings of context words cat and on are [1,2] and [3,0]. Compute the CBOW hidden vector using mean aggregation. Output vectors for [sat,ran] are [1,0] and [0,1]. Compute softmax probabilities.
Given
Context embeddings [1,2], [3,0]; mean aggregation; two candidate output vectors.
To find
The hidden vector, logits and probabilities.
Formula and why it applies
Mean context vector 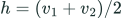 LaTeX:
h=(v_1+v_2)/2. Logit  LaTeX:
z_w=u_w^Th. Softmax 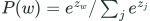 LaTeX:
P(w)=e^{z_w}/\sum_j e^{z_j}.
Step 1. Add coordinates
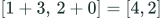 LaTeX:
[1+3,\,2+0]=[4,2].
Step 2. Divide by number of words
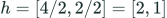 LaTeX:
h=[4/2,2/2]=[2,1].
Step 3. Compute logits
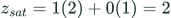 LaTeX:
z_{sat}=1(2)+0(1)=2. 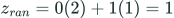 LaTeX:
z_{ran}=0(2)+1(1)=1.
Step 4. Exponentials
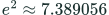 LaTeX:
e^2\approx7.389056, 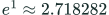 LaTeX:
e^1\approx2.718282; sum  LaTeX:
\approx10.107338.
Step 5. Divide
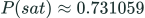 LaTeX:
P(sat)\approx0.731059, 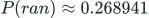 LaTeX:
P(ran)\approx0.268941.
Answer. h=[2,1]; sat is more probable (0.731059).
Question. A skip-gram centre embedding is v=[1,−1]. Output embeddings for [eat,sleep,drive] are [1,1], [0,1], [1,0]. Calculate the predicted context probabilities.
Given
One centre vector and three output vectors; full softmax over these three words.
To find
Three logits and three probabilities.
Formula and why it applies
 LaTeX:
z_j=u_j^Tv, then 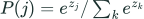 LaTeX:
P(j)=e^{z_j}/\sum_k e^{z_k}.
Step 1. Eat dot product
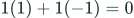 LaTeX:
1(1)+1(-1)=0.
Step 2. Sleep and drive dot products
 LaTeX:
z_{sleep}=0(1)+1(-1)=-1. 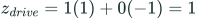 LaTeX:
z_{drive}=1(1)+0(-1)=1.
Step 3. Exponentiate and sum
 LaTeX:
e^0=1, 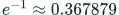 LaTeX:
e^{-1}\approx0.367879, LaTeX: e^1\approx2.718282. Sum  LaTeX:
\approx4.086161.
Step 4. Normalize
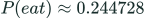 LaTeX:
P(eat)\approx0.244728; 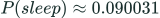 LaTeX:
P(sleep)\approx0.090031; 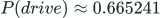 LaTeX:
P(drive)\approx0.665241.
Answer. drive has the highest probability in this toy learned model.
Limitations: a standard static Word2Vec vector merges a word's senses; it has limited representation of subword morphology and out-of-vocabulary words; its local prediction objective does not directly fit a full global co-occurrence table. Similarity is learned from data and is not a guarantee of factual or causal understanding.
CBOW = neighbours se missing centre. Skip-gram = centre se neighbours.