Natural Language Processing · TEE · papers
Q6b · BoW and TF–IDF movie corpus
2022-11-22 · final · recovered AI paper
Previous examination · complete worked answers
Question. Find Bag of Words and TF–IDF for: “This movie is very scary and long”; “This movie is not scary and is slow”; “This movie is spooky and good”. [10 marks]
Answer
Given
| Document | Original text |
|---|---|
| 1 | This movie is very scary and long |
| 2 | This movie is not scary and is slow |
| 3 | This movie is spooky and good |
Stopwords: none supplied
To find
BoW, IDF and TF–IDF
Formula: which one and why
Use lowercase alphabetic tokens and exactly the stated stoplist. If no stoplist is supplied, retain function words. Adopt raw-count TF and natural-log IDF; the paper does not prescribe another TF/log convention.
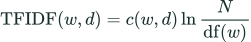 LaTeX:
\mathrm{TFIDF}(w,d)=c(w,d)\ln\frac{N}{\mathrm{df}(w)}A term shared by all N documents has IDF ln(1)=0. Counts and TF–IDF weights are different representations.
Step 1. Tokenize each document
| Document | Tokens |
|---|---|
| 1 | this, movie, is, very, scary, and, long |
| 2 | this, movie, is, not, scary, and, is, slow |
| 3 | this, movie, is, spooky, and, good |
Step 2. Fix the vocabulary order
and, good, is, long, movie, not, scary, slow, spooky, this, very
Step 3. Count occurrences (Bag of Words)
| Document | and | good | is | long | movie | not | scary | slow | spooky | this | very |
|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | 1 | 0 | 1 | 1 | 1 | 0 | 1 | 0 | 0 | 1 | 1 |
| 2 | 1 | 0 | 2 | 0 | 1 | 1 | 1 | 1 | 0 | 1 | 0 |
| 3 | 1 | 1 | 1 | 0 | 1 | 0 | 0 | 0 | 1 | 1 | 0 |
Step 4. Calculate document frequency and IDF
| Term | df | N / df | ln(N/df) |
|---|---|---|---|
| and | 3 | 1 | 0.000000000 |
| good | 1 | 3 | 1.098612289 |
| is | 3 | 1 | 0.000000000 |
| long | 1 | 3 | 1.098612289 |
| movie | 3 | 1 | 0.000000000 |
| not | 1 | 3 | 1.098612289 |
| scary | 2 | 3/2 | 0.405465108 |
| slow | 1 | 3 | 1.098612289 |
| spooky | 1 | 3 | 1.098612289 |
| this | 3 | 1 | 0.000000000 |
| very | 1 | 3 | 1.098612289 |
Step 5. Multiply each TF by its IDF
| Document | and | good | is | long | movie | not | scary | slow | spooky | this | very |
|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | 0.000000 | 0.000000 | 0.000000 | 1.098612 | 0.000000 | 0.000000 | 0.405465 | 0.000000 | 0.000000 | 0.000000 | 1.098612 |
| 2 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 1.098612 | 0.405465 | 1.098612 | 0.000000 | 0.000000 | 0.000000 |
| 3 | 0.000000 | 1.098612 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 1.098612 | 0.000000 | 0.000000 |
Final answer
The final table is the TF–IDF matrix in the declared vocabulary order. A different explicitly stated log base rescales all IDFs; length-normalized TF changes each document scale.