Natural Language Processing · TEE · papers
Q7a · POS, chunks and boundary-aware HMM
2024-12-03 · final · recovered AI paper
Previous examination · complete worked answers
Answer
Part-of-speech (POS) tagging assigns a grammatical category to every word token in context, such as noun, verb, adjective or determiner. It is a sequence-labeling task: the input is a sequence of words, and the output is a tag for each word. A tag describes the word's role in this sentence, not its meaning in every possible sentence.
| Tag | Role | Example in context |
|---|---|---|
| NN / NNS | Singular / plural common noun | a book / two books |
| NNP | Proper noun | Mary, Mumbai |
| VB / VBD / VBZ | Base / past / third-person singular verb | read / read / reads |
| JJ | Adjective | the red book |
| RB | Adverb | runs quickly |
| DT | Determiner | the, a, this |
| IN | Preposition or subordinating conjunction | on the table |
| PRP | Personal pronoun | she, they |
| MD | Modal auxiliary | can, will, should |
Open classes readily accept new content words: nouns, verbs, adjectives and adverbs. Examples include chatbot and livestream. Closed classes contain comparatively stable grammatical/function words: determiners, pronouns, prepositions and conjunctions. These are tendencies, not a claim that language never changes.
Compare “hand me that book”: book is a noun here. Similarly, “I can swim” has can/MD, while “the can is empty” has can/NN. The spelling stays the same; neighboring words and sentence structure change the correct tag. This is POS ambiguity.
| Sentence | Tagged interpretation | Reason |
|---|---|---|
| They watch birds. | They/PRP watch/VBP birds/NNS | watch is the action. |
| The watch stopped. | The/DT watch/NN stopped/VBD | watch is the object that stopped. |
| She has a light bag. | She/PRP has/VBZ a/DT light/JJ bag/NN | light describes bag. |
| Light the lamp. | Light/VB the/DT lamp/NN | Light is an imperative verb. |
POS tags support parsing, named entity recognition, question answering, sentiment analysis and word-sense disambiguation. They do not by themselves identify every entity or fully resolve meaning.
Yaad rakho: Word ka naam same ho sakta hai; sentence mein uska kaam tag decide karta hai.
Chunking, also called shallow parsing, groups adjacent tagged words into meaningful non-overlapping units, commonly noun phrases. It usually identifies local phrase boundaries without producing the complete hierarchical structure of a sentence. Chinking removes specified tokens from an existing candidate chunk, splitting or trimming it.
A POS tagger labels individual words. A chunker groups words into phrases. A full parser shows how phrases relate recursively to form the entire sentence. These are related tasks with different outputs.
| Operation | Input | Output |
|---|---|---|
| POS tagging | The small cat | The/DT small/JJ cat/NN |
| NP chunking | Tagged tokens | [NP The small cat] |
| Chinking | A broad candidate chunk | Remove verbs/prepositions, keep noun-phrase segments |
| Full parsing | Sentence + grammar | A nested tree with sentence, noun phrase and verb phrase nodes |
Rule-based chunking uses tag patterns. Statistical or learned chunkers infer boundaries from labeled examples. A useful NP rule is an optional determiner, followed by zero or more adjectives, followed by a noun. In NLTK-style notation: NP: {<DT>?<JJ>*<NN>}. Here ? means zero or one occurrence; * means zero or more; + means one or more when used. The braces mean “form a chunk around the matched sequence”.
Question. Apply the NP rule optional DT, zero or more JJ, then one NN to “The/DT quick/JJ brown/JJ fox/NN jumps/VBZ over/IN the/DT lazy/JJ dog/NN”.
Given
Tagged input is supplied. Rule: DT? JJ* NN.
To find
All noun-phrase chunks.
Formula and why it applies
NP → DT? JJ* NN
The rule groups a noun with its preceding determiner and adjectives; a verb or preposition does not match this NP pattern.
Solution
Step 1. Start at The
The matches optional DT; quick and brown both match JJ*; fox matches NN.
Step 2. Form the first NP
[NP The quick brown fox]
Step 3. Skip nonmatching tokens
jumps/VBZ and over/IN do not satisfy the NP pattern.
Step 4. Match the second NP
the is DT, lazy is JJ, dog is NN: [NP the lazy dog].
Question. Using NP → DT? JJ* NN, identify the chunks in “bright/JJ stars/NN shine/VBP and/CC a/DT moon/NN glows/VBZ”. Use the supplied tags exactly.
Given
Input tags label stars as NN for this exercise. Rule requires optional DT, zero or more JJ, then NN.
To find
The matched NP spans.
Formula and why it applies
NP → DT? JJ* NN
The optional determiner may be absent and the adjective repetition may be empty.
Solution
Step 1. Match bright stars
No determiner is present, which DT? permits. bright matches JJ; stars matches NN.
Step 2. Inspect shine and and
VBP and CC fall outside the NP rule.
Step 3. Match a moon
a matches DT; no adjective is present; moon matches NN.
Question. Begin with one candidate chunk containing “The/DT cat/NN sat/VBD on/IN the/DT mat/NN”. Chink out verbs and prepositions. Show the remaining chunks.
Given
Initial candidate: [The cat sat on the mat]. Remove tags VBD and IN.
To find
The chunk segments after exclusion.
Formula and why it applies
Chinking removes matched tokens from the existing chunk.
Removing the middle verb/preposition region divides the original candidate into two remaining contiguous spans.
Solution
Step 1. Locate the tokens to remove
sat is VBD and on is IN.
Step 2. Remove those tokens from chunk membership
The remaining token groups are “The cat” and “the mat”. sat and on still exist in the sentence; they are simply outside these chunks.
Step 3. Write the final chunked sentence
[The cat] sat on [the mat].
Yaad rakho: Chunking = andar group karo; chinking = unwanted tokens ko group se bahar karo.
Exact HMM table
Given
| Sentence | Supplied tags |
|---|---|
| Book a flight | Verb Det Noun |
| Read the book | Verb Det Noun |
| The book is green | Det Noun Modal-Verb Noun |
To find
Transition and emission probability tables including START and END.
Formula: which one and why
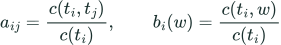 LaTeX:
a_{ij}=\frac{c(t_i,t_j)}{c(t_i)},\qquad b_i(w)=\frac{c(t_i,w)}{c(t_i)}For START divide by sentence count. END has no outgoing or emission distribution. Keep the supplied tags even when their linguistic choice is unusual, and retain case-sensitive Book/book and The/the as printed.
Step 1. Add boundary tags to every sentence
START Verb Det Noun END
START Verb Det Noun END
START Det Noun Modal-Verb Noun END
Step 2. Count transitions
| From → to | Count |
|---|---|
| START → Verb | 2 |
| Verb → Det | 2 |
| Det → Noun | 3 |
| Noun → END | 3 |
| START → Det | 1 |
| Noun → Modal-Verb | 1 |
| Modal-Verb → Noun | 1 |
Step 3. Divide by each source tag count
| From | Denominator | Verb | Det | Noun | Modal-Verb | END |
|---|---|---|---|---|---|---|
| START | 3 | 2/3 | 1/3 | 0 | 0 | 0 |
| Verb | 2 | 0 | 1 | 0 | 0 | 0 |
| Det | 3 | 0 | 0 | 1 | 0 | 0 |
| Noun | 4 | 0 | 0 | 0 | 1/4 | 3/4 |
| Modal-Verb | 1 | 0 | 0 | 1 | 0 | 0 |
Step 4. Count and normalize emissions
| Tag | Count | Book | a | flight | Read | the | book | The | is | green |
|---|---|---|---|---|---|---|---|---|---|---|
| Verb | 2 | 1/2 | 0 | 0 | 1/2 | 0 | 0 | 0 | 0 | 0 |
| Det | 3 | 0 | 1/3 | 0 | 0 | 1/3 | 0 | 1/3 | 0 | 0 |
| Noun | 4 | 0 | 0 | 1/4 | 0 | 0 | 1/2 | 0 | 0 | 1/4 |
| Modal-Verb | 1 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 1 | 0 |
Final answer
Every nonterminal transition row sums to1 when END is included; every emission row sums to1. Boundary symbols do not emit lexical words.
POS applications include syntax parsing, disambiguation, lemmatization, chunking and extraction. For this numerical retain printed green=Noun and is=Modal-Verb even though ordinary linguistic tagging would differ; the task is estimation from supplied labels.
Source / convention note. Printed tags are used as training data; START and END are explicitly required and included.