Natural Language Processing · TEE · papers
Q3b · Naive Bayes text classifier
2023-01-30 · re-exam · recovered AI paper
Previous examination · complete worked answers
Answer
The paper supplies no numerical training corpus for this part. The following clearly labelled illustrative corpus demonstrates the complete calculation.
Given
| Training text | Class |
|---|---|
| Chinese Beijing Chinese | yes |
| Chinese Chinese Shanghai | yes |
| Chinese Macao | yes |
| Tokyo Japan Chinese | no |
Test: Chinese Chinese Chinese Tokyo Japan
To find
Classify the test using multinomial Naive Bayes.
Formula: which one and why
Assume add-one smoothing unless the question supplies probabilities. Keep repeated words as repeated factors. Use training vocabulary only; ignore out-of-vocabulary words unless an unknown-token model is defined.
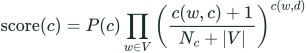 LaTeX:
\mathrm{score}(c)=P(c)\prod_{w\in V}\left(\frac{c(w,c)+1}{N_c+|V|}\right)^{c(w,d)}Step 1. Vocabulary and class priors
V = {beijing, chinese, japan, macao, shanghai, tokyo}; |V|=6.
| Class | Documents | Prior |
|---|---|---|
| no | 1 | 1/4 |
| yes | 3 | 3/4 |
Step 2. Count every training word within each class
| Class | Total tokens | beijing | chinese | japan | macao | shanghai | tokyo |
|---|---|---|---|---|---|---|---|
| no | 3 | 0 | 1 | 1 | 0 | 0 | 1 |
| yes | 8 | 1 | 5 | 0 | 1 | 1 | 0 |
Step 3. Count the test words
| Word | Count |
|---|---|
| chinese | 3 |
| tokyo | 1 |
| japan | 1 |
OOV words: none
Step 4. Calculate likelihoods and multiply with the prior
| Class | Prior | Individual factors | Exact score | Decimal score |
|---|---|---|---|---|
| no | 1/4 | chinese: (1+1)/(3+1×6) = 2/9, used 3 time(s); tokyo: (1+1)/(3+1×6) = 2/9, used 1 time(s); japan: (1+1)/(3+1×6) = 2/9, used 1 time(s) | 8/59049 | 0.000135480702467 |
| yes | 3/4 | chinese: (5+1)/(8+1×6) = 3/7, used 3 time(s); tokyo: (0+1)/(8+1×6) = 1/14, used 1 time(s); japan: (0+1)/(8+1×6) = 1/14, used 1 time(s) | 81/268912 | 0.000301213779973 |
Step 5. Compare and optionally normalize
Normalized scores: no = 0.310241388, yes = 0.689758612
Division by the same total does not change the winning class.
Final answer
Predicted class: yes.
Yaad rakho: Count → prior → smoothed word chances → repeated factors → compare.
Source / convention note. Chinese corpus is an authored/reused teaching illustration here; it is actual given data in F22 Q5b, not this prompt.