Natural Language Processing · TEE · papers
Q1a · BoW and one-hot encoding
2025-02-21 · re-exam · recovered AI paper
Previous examination · complete worked answers
Answer
Bag of words (BoW) represents a document by the counts of vocabulary terms, discarding their positions. A binary BoW variant stores only presence/absence; a count BoW stores frequencies. State which is used.
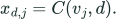 LaTeX:
x_{d,j}=C(v_j,d). LaTeX:
x_{d,j} is document  LaTeX:
d's coordinate for vocabulary term  LaTeX:
v_j.  LaTeX:
C(v_j,d) is its occurrence count.
A bag of n-grams uses short contiguous token sequences as features. Bigrams can distinguish “not good” from “good”, but increasing n enlarges the vocabulary and creates more rare features.
Question. Build count and binary BoW for D1=“cat cat dog” and D2=“dog fish”. Use vocabulary [cat,dog,fish] and no stopword removal.
Given
Two tokenized documents, fixed vocabulary order.
To find
Count vectors and binary vectors.
Formula and why it applies
Count BoW uses LaTeX: C(v_j,d). Binary BoW is 1 when that count is positive and 0 otherwise.
Step 1. D1 counts
cat=2, dog=1, fish=0 → [2,1,0].
Step 2. D2 counts
cat=0, dog=1, fish=1 → [0,1,1].
Step 3. Convert to presence
D1 [1,1,0]; D2 [0,1,1].
Answer. Count rows [2,1,0], [0,1,1]; binary rows [1,1,0], [0,1,1].
Question. After lowercasing and removing {is,a,means}, obtain BoW vectors for D1=“Continuous learning is learning lifetime”, D2=“Continuous learning means lifetime learning”, D3=“Learning is a good practice”. Use [continuous,good,learning,lifetime,practice].
Given
Three documents and exact stopword set from the supplied slides.
To find
The document–term count matrix.
Formula and why it applies
Remove only the listed stopwords, then count every remaining token in the fixed column order.
Step 1. Clean D1
[continuous,learning,learning,lifetime] → [1,0,2,1,0].
Step 2. Clean D2
[continuous,learning,lifetime,learning] → [1,0,2,1,0].
Step 3. Clean D3
[learning,good,practice] → [0,1,1,0,1].
Step 4. Compare D1 and D2
They have identical BoW vectors despite different original wording/order.
Answer. Rows [1,0,2,1,0], [1,0,2,1,0], [0,1,1,0,1].
Question. Build a bag of bigrams for “not good but not bad” with vocabulary [not good,good but,but not,not bad]. Do not add sentence boundary tokens.
Given
Five tokens; use adjacent pairs, stride 1.
To find
The bigram count vector.
Formula and why it applies
A sequence of  LaTeX:
L tokens has  LaTeX:
L-1 adjacent bigrams when no boundaries are added.
Step 1. Enumerate pairs
(not,good), (good,but), (but,not), (not,bad).
Step 2. Count each vocabulary bigram
Each appears once.
Step 3. Write vector
[1,1,1,1].
Answer. Four bigram features, each with count 1.
BoW: order bhool, word-count rakh. Bag of bigrams: neighbouring word-pair count.
Label encoding assigns each category or word a unique integer ID. One-hot encoding assigns a length- LaTeX:
V vector with one 1 at the word's vocabulary position and zeros elsewhere.
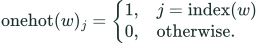 LaTeX:
\operatorname{onehot}(w)_j=\begin{cases}1,&j=\operatorname{index}(w)\\0,&\text{otherwise.}\end{cases}The index is an ID, not a meaning score. One-hot represents one token/category; a multiword document generally needs multiple token vectors or an aggregation scheme.
Question. Encode “dog cat dog” using vocabulary [cat,dog,fish], IDs starting at 0. Give label IDs and a one-hot vector for every token.
Given
cat→0, dog→1, fish→2. Vector columns have the same order.
To find
The ID sequence and three one-hot rows.
Formula and why it applies
Replace each word by its ID for labels; set its vocabulary position to 1 for one-hot.
Step 1. Label IDs
dog→1, cat→0, dog→1 → [1,0,1].
Step 2. First dog
[0,1,0].
Step 3. Cat
[1,0,0].
Step 4. Second dog
[0,1,0]. Repeated tokens keep the same representation.
Answer. IDs [1,0,1]; one-hot rows [0,1,0], [1,0,0], [0,1,0].
Question. Encode the city sequence Mumbai, Delhi, Mumbai, Pune using vocabulary [Delhi,Mumbai,Pune] and label IDs starting at 1.
Given
Delhi→1, Mumbai→2, Pune→3.
To find
IDs and one-hot rows.
Formula and why it applies
One-hot uses three coordinates regardless of whether label IDs begin at 0 or 1.
Step 1. IDs
[2,1,2,3].
Step 2. Mumbai rows
Each Mumbai → [0,1,0].
Step 3. Delhi and Pune
Delhi→[1,0,0]; Pune→[0,0,1].
Answer. Rows [0,1,0], [1,0,0], [0,1,0], [0,0,1].
Question. One-hot encode categories [red,green,blue] for a linear regression with an intercept. Then give dummy coding after dropping blue.
Given
Full column order [red,green,blue]. Blue is the baseline.
To find
Full and reduced codes.
Formula and why it applies
Full one-hot rows sum to 1. With an intercept this creates a linear dependency; dropping one category column gives k−1 independent dummy indicators.
Step 1. Full encoding
| Category | red | green | blue |
|---|---|---|---|
| red | 1 | 0 | 0 |
| green | 0 | 1 | 0 |
| blue | 0 | 0 | 1 |
Step 2. Drop blue column
| Category | red | green |
|---|---|---|
| red | 1 | 0 |
| green | 0 | 1 |
| blue | 0 | 0 |
Step 3. Interpret zero row
[0,0] now identifies the baseline blue, not missing data.
Answer. Full width 3; reduced dummy width 2. Dropping a column is model-dependent, not a requirement for every neural embedding input.
Limitations: one-hot is large and sparse and does not express semantic similarity. Unseen words need a defined unknown-token or vocabulary-update policy. Label IDs are compact but should not be treated as an ordered scalar feature for nominal words.
Label = ID number. One-hot = us ID ke box mein 1, baaki 0.