Natural Language Processing · TEE · papers
Q1c · Syntax parsing approaches
2025-02-21 · re-exam · recovered AI paper
Previous examination · complete worked answers
Answer
A context-free grammar (CFG) specifies a language using production rules whose left side is a single nonterminal. Formally, G=(N,Σ,R,S): N is the set of nonterminals, Σ the terminal vocabulary, R the production rules, and S the start symbol. A rule can expand its nonterminal regardless of the neighboring symbols; that is the meaning of “context-free”.
| Concept | Plain explanation | Example |
|---|---|---|
| Terminal | A word at a leaf; it is not expanded further | the, girl, read |
| Nonterminal | A grammatical category that can be expanded | S, NP, VP, Det, N, V |
| Production | A permitted replacement | S → NP VP |
| Start symbol | Category for a complete sentence | S |
| Lexicon | Word-to-category rules | N → girl | paper |
| Derivation | Sequence of rule applications | S ⇒ NP VP ⇒ Det N VP ⇒ … |
| Parse tree | Hierarchical picture of those expansions | Root S, internal phrases, word leaves |
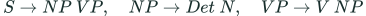 LaTeX:
S\to NP\ VP,\quad NP\to Det\ N,\quad VP\to V\ NPRead S→NP VP as “a sentence can contain a noun phrase followed by a verb phrase”. It does not mean subtraction or multiplication. A vertical bar in a grammar rule means alternatives: Det→the | a allows either the or a. This is different from the probability bar meaning “given”.
A constituent is a group of words that acts as a grammatical unit, such as “the girl”. Syntactic parsing assigns a grammatical structure to an input sentence using a grammar. It can support grammar checking, information extraction, translation and later semantic analysis. Failure under one restricted grammar means that grammar could not derive the sentence; it does not necessarily prove the sentence is invalid English.
A treebank is a corpus annotated with parse trees. It supplies training/evaluation structures for parsers and lets linguists study recurring syntactic patterns. A tagged corpus gives word tags; a treebank additionally records relationships among phrases.
| Representation | Example information retained |
|---|---|
| Bag of words | Words occur, but word order/grammar is lost |
| POS tags | Each word's local grammatical category |
| Chunks | Short phrase boundaries |
| Parse tree | Nested constituent structure of the whole sentence |
Yaad rakho: Grammar rule ek expansion instruction hai: S ko NP aur VP mein kholo.
Top-down parsing starts at the grammar's start symbol S and expands nonterminals until the leaves match the input words in order. Recursive descent commonly implements each nonterminal as a procedure that tries its productions. It builds from the root toward the leaves.
Algorithm. Start with S as the current goal. Choose a production for the leftmost unexpanded nonterminal. Replace that nonterminal by the production's right side. If a terminal appears, compare it with the next input token. If it matches, consume the token; if it does not, reject that branch and try another production. Accept only when the complete input is consumed and all grammar goals are satisfied.
A leftmost derivation always expands the leftmost remaining nonterminal first. Top-down parsing can make guesses that the actual words cannot support, so it may need backtracking. A naive recursive-descent parser can loop on left-recursive rules such as NP→NP PP unless the grammar or algorithm is changed. Predictive LL(1) parsing chooses productions using one lookahead token when the grammar permits; not every English CFG is LL(1).
| Approach | Begins with | Direction | Common difficulty |
|---|---|---|---|
| Top-down | Start symbol S | Root to word leaves | Predictions that do not match input; left recursion |
| Bottom-up | Actual input tokens | Leaves to root S | Reductions that cannot contribute to a complete sentence |
Yaad rakho: Top-down: sentence ka structure pehle, words tak neeche aao.
Bottom-up parsing starts from the input tokens and combines them into larger constituents until the start symbol is reached. A shift-reduce parser maintains a stack of recognized material and a list of remaining input tokens.
| Action | Exact operation | Example |
|---|---|---|
| Shift | Move the next input token onto the stack | Stack: the; remaining input: dog runs |
| Reduce | Replace a suffix of the stack matching a rule's RHS with its LHS | Det N becomes NP using NP→Det N |
| Accept | Stack is S and input is exhausted | Stack: S; input: empty |
| Fail/backtrack | Chosen reductions cannot complete a parse | A noun reading of book blocks an imperative parse |
Reduction uses a production in reverse: the grammar NP→Det N expands an NP top-down, but reduces Det N into NP bottom-up. The stack's rightmost item is its top in the traces below. Each row shows the state after the listed action, avoiding an off-by-one mismatch between actions and stack contents.
A lexical reduction such as N→dog still counts as a reduction. Do not skip the sequence from word to category to phrase when the question asks for a complete trace. Backtracking means returning to an earlier choice and trying another applicable rule, not changing the original input.
Yaad rakho: Shift = input se stack. Reduce = chhote pieces se bada grammatical unit.