Natural Language Processing · TEE · read
Generative versus discriminative models and Bayes' rule
POS tagging and its learning approaches
Unit 4, pages 3–46
Let x be the observed words and y be the desired tag sequence. A generative model describes their joint distribution P(x,y), often as P(y)P(x|y). A discriminative model learns P(y|x) directly or learns a decision boundary that separates possible labels. Both kinds can be trained with labeled data; “generative” does not mean “always unsupervised”.
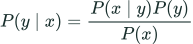 LaTeX:
P(y\mid x)=\frac{P(x\mid y)P(y)}{P(x)}| Quantity | Meaning | POS interpretation |
|---|---|---|
| P(y) | Prior | How plausible is this tag or tag sequence before seeing the words? |
| P(x|y) | Likelihood | How plausible are these words under that tag sequence? |
| P(x) | Evidence | Total probability of the observed words across possible labels. |
| P(y|x) | Posterior | Probability of the tags after seeing the words. |
| Aspect | Generative | Discriminative |
|---|---|---|
| Models | Joint P(x,y), or prior × likelihood | Conditional P(y|x) or decision boundary |
| Classification examples | Naive Bayes | Logistic regression, SVM |
| Sequence-labeling examples | HMM | Linear-chain CRF |
| Intuition | Model how a label could generate the observation | Model which label fits the observation |
Question. A token has two possible tags, noun N and verb V. P(N)=0.6, P(V)=0.4, P(book|N)=0.2 and P(book|V)=0.5. Calculate P(N|book) and P(V|book).
Given
Two tags are exhaustive. Priors: 0.6,0.4. Word likelihoods: 0.2,0.5.
To find
Normalized posterior probabilities.
Formula and why it applies
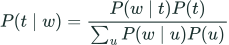 LaTeX:
P(t\mid w)=\frac{P(w\mid t)P(t)}{\sum_{u}P(w\mid u)P(u)}Bayes' rule combines prior and likelihood. Normalization is needed to convert scores into posterior probabilities.
Solution
Step 1. Calculate the noun score
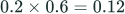 LaTeX:
0.2\times0.6=0.12Step 2. Calculate the verb score
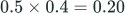 LaTeX:
0.5\times0.4=0.20Step 3. Find the evidence
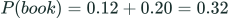 LaTeX:
P(book)=0.12+0.20=0.32Step 4. Normalize the noun score
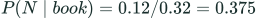 LaTeX:
P(N\mid book)=0.12/0.32=0.375Step 5. Normalize the verb score
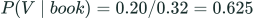 LaTeX:
P(V\mid book)=0.20/0.32=0.625Question. Two candidate tags have prior-likelihood products 0.06 and 0.14. Find their normalized probabilities.
Given
Unnormalized scores s₁=0.06 and s₂=0.14; these are the only candidates.
To find
The two posterior probabilities.
Formula and why it applies
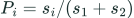 LaTeX:
P_i=s_i/(s_1+s_2)A common denominator converts the candidate scores to a distribution summing to one.
Solution
Step 1. Add scores
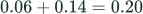 LaTeX:
0.06+0.14=0.20Step 2. Normalize first
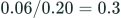 LaTeX:
0.06/0.20=0.3Step 3. Normalize second
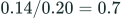 LaTeX:
0.14/0.20=0.7Yaad rakho: Generative: tag se word ka model. Discriminative: word se tag ka decision.
Bayes Rule & Models
- id
- nlp-m2-02-bayes-generative-discriminative
- title
- Bayes Rule & Models
- title_confirmed
- true
- topic_title
- Bayes rule and generative versus discriminative models
- mode
- m2
- kind
- focused
- status
- available
- duration
- 10:51
- reviewed
- false
- notebook_url
- https://notebook.google.com/notebook/a270ef1e-c285-4d31-9db1-302090c5f8b1
- youtube_url
- corrected_visuals
- false
- upload_pending_correction
- false
- correction_note
- related_topic_ids
These are recorded generation statuses, not a live service check. Private YouTube and signed-in NotebookLM links require the owner's account. This export publishes existing catalog metadata, not private video files or an invented transcript.
NLP M2 — Probability and Bayes | Reviewed step-by-step numericals
- id
- overview-probability-bayes
- title
- NLP M2 — Probability and Bayes | Reviewed step-by-step numericals
- title_confirmed
- true
- topic_title
- NLP M2 — Probability and Bayes | Reviewed step-by-step numericals
- mode
- m2
- kind
- supplemental
- status
- available
- duration
- 8:53
- reviewed
- true
- notebook_url
- https://notebook.google.com/notebook/a270ef1e-c285-4d31-9db1-302090c5f8b1
- youtube_url
- corrected_visuals
- true
- upload_pending_correction
- true
- correction_note
- Complete HMM and Naive Bayes calculations; clarified joint scores versus model posteriors. Full transcript and detected slides checked; short voice corrections included. The corrected YouTube upload is still processing.
- related_topic_ids
- nlp-m2-01-foundations-counts-probability
- nlp-m2-02-bayes-generative-discriminative
These are recorded generation statuses, not a live service check. Private YouTube and signed-in NotebookLM links require the owner's account. This export publishes existing catalog metadata, not private video files or an invented transcript.