Natural Language Processing · TEE · read
More WSD numericals: given likelihoods, unequal priors and repeated clues
Naive Bayes WSD: probabilities to a complete numerical
Unit 5 · PDF pages 49–57
Question. For bass, let P(Fish)=0.6 and P(Music)=0.4. Given Fish likelihoods P(caught|Fish)=0.5, P(lake|Fish)=0.4 and Music likelihoods P(caught|Music)=0.05, P(lake|Music)=0.1, classify context {caught,lake} and normalize.
Given
Priors and likelihoods are provided directly; no smoothing or training-count estimation is requested.
To find
The winning sense and its posterior.
Formula and why it applies
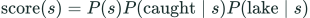 LaTeX:
\operatorname{score}(s)=P(s)P(\text{caught}\mid s)P(\text{lake}\mid s), because the two features are treated as conditionally independent.
Step 1. Fish multiplication
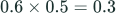 LaTeX:
0.6\times0.5=0.3, then 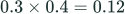 LaTeX:
0.3\times0.4=0.12.
Step 2. Music multiplication
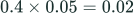 LaTeX:
0.4\times0.05=0.02, then 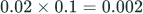 LaTeX:
0.02\times0.1=0.002.
Step 3. Total evidence
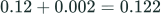 LaTeX:
0.12+0.002=0.122.
Step 4. Normalize
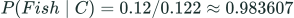 LaTeX:
P(Fish\mid C)=0.12/0.122\approx0.983607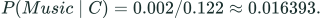 LaTeX:
P(Music\mid C)=0.002/0.122\approx0.016393.Answer. Fish, with model posterior approximately 0.983607.
Question. Disambiguate bank from the repeated context tokens {loan, loan, river}. Priors are Finance=2/3 and River=1/3. Vocabulary V=4. Finance has N=8 total tokens, loan count 3 and river count 0; River has N=4, loan count 0 and river count 2. Apply add-one smoothing.
Given
Multinomial counts are supplied. The two appearances of loan must both contribute.
To find
Scores and normalized Finance posterior.
Formula and why it applies
Naive Bayes selects the sense with the largest prior × likelihood product. The context evidence denominator is identical across candidate senses, so it can be omitted for comparison.
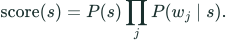 LaTeX:
\operatorname{score}(s)=P(s)\prod_j P(w_j\mid s).For add-one multinomial smoothing:
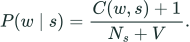 LaTeX:
P(w\mid s)=\frac{C(w,s)+1}{N_s+V}. LaTeX:
C(w,s) counts occurrences of word  LaTeX:
w in training contexts of sense  LaTeX:
s;  LaTeX:
N_s is the total number of word occurrences in those contexts;  LaTeX:
V is the shared vocabulary size. It is not the number of training sentences. Repeated query words contribute repeated factors.
Step 1. Finance denominator
 LaTeX:
8+4=12. 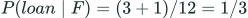 LaTeX:
P(loan\mid F)=(3+1)/12=1/3; 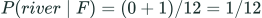 LaTeX:
P(river\mid F)=(0+1)/12=1/12.
Step 2. River denominator
 LaTeX:
4+4=8. 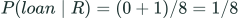 LaTeX:
P(loan\mid R)=(0+1)/8=1/8; 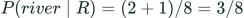 LaTeX:
P(river\mid R)=(2+1)/8=3/8.
Step 3. Finance product
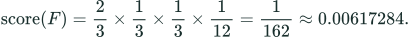 LaTeX:
\operatorname{score}(F)=\frac23\times\frac13\times\frac13\times\frac1{12}=\frac1{162}\approx0.00617284.Step 4. River product
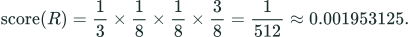 LaTeX:
\operatorname{score}(R)=\frac13\times\frac18\times\frac18\times\frac38=\frac1{512}\approx0.001953125.Step 5. Compare and normalize
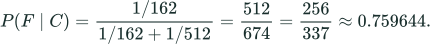 LaTeX:
P(F\mid C)=\frac{1/162}{1/162+1/512}=\frac{512}{674}=\frac{256}{337}\approx0.759644.Answer. Finance wins. Repeated loan contributes a squared likelihood; do not reduce the query to a unique-word set.
Answer-writing order in an exam
Write the class priors, vocabulary size, class token totals, a likelihood table, both score products and the final class. Keep fractions until the comparison where possible. If the question only asks classification, normalization is optional; if it asks posterior probabilities, normalization is required.
Repeated word aaye toh factor bhi repeat. Sirf word-set bana diya toh multinomial answer badal jayega.
Naive Bayes WSD Numerical
- id
- nlp-m2-18-naive-bayes-wsd
- title
- Naive Bayes WSD Numerical
- title_confirmed
- true
- topic_title
- Naive Bayes WSD: a complete corpus numerical
- mode
- m2
- kind
- focused
- status
- available
- duration
- 11:35
- reviewed
- false
- notebook_url
- https://notebook.google.com/notebook/a270ef1e-c285-4d31-9db1-302090c5f8b1
- youtube_url
- corrected_visuals
- false
- upload_pending_correction
- false
- correction_note
- related_topic_ids
These are recorded generation statuses, not a live service check. Private YouTube and signed-in NotebookLM links require the owner's account. This export publishes existing catalog metadata, not private video files or an invented transcript.
NLP M2 — Word-sense disambiguation | Reviewed Lesk and Bayes numericals
- id
- overview-wsd
- title
- NLP M2 — Word-sense disambiguation | Reviewed Lesk and Bayes numericals
- title_confirmed
- true
- topic_title
- WSD: Detective Math Toolkit
- mode
- m2
- kind
- supplemental
- status
- available
- duration
- 6:11
- reviewed
- true
- notebook_url
- https://notebook.google.com/notebook/a270ef1e-c285-4d31-9db1-302090c5f8b1
- youtube_url
- https://www.youtube.com/watch?v=jUPghV2wIkY
- corrected_visuals
- true
- upload_pending_correction
- false
- correction_note
- Lesk variants, conditional Bayes definitions, smoothing and both worked posteriors; corrected spoken claims. Full transcript and detected slides checked; short voice corrections included.
- related_topic_ids
- nlp-m2-16-lesk-wsd
- nlp-m2-17-walker-graph-wsd
- nlp-m2-18-naive-bayes-wsd
These are recorded generation statuses, not a live service check. Private YouTube and signed-in NotebookLM links require the owner's account. This export publishes existing catalog metadata, not private video files or an invented transcript.